Glassdoor is primarily recognized for hosting company reviews from former and current employees, but it offers a wealth of additional information including company metadata, salary data, and comprehensive reviews. This extensive data repository makes Glassdoor an excellent target for web scraping operations!
In this comprehensive web scraping guide, we’ll explore glassdoor.com and demonstrate how to extract company information, job postings, and reviews. We’ll accomplish this using Python alongside several popular community libraries, so let’s get started.
Key Takeaways
Master the extraction of Glassdoor company data, job listings, and reviews using Python with httpx and parsel, while handling dynamic content and anti-bot measures for employment data collection.
- Reverse engineer Glassdoor’s search API endpoints by intercepting browser network requests
- Parse dynamic JSON data embedded in HTML using XPath selectors for job details and company information
- Bypass Glassdoor’s anti-scraping measures with realistic headers, user agents, and request spacing
- Extract structured employment data including job titles, salaries, company reviews, and ratings
- Implement exponential backoff retry logic with 403 status code detection for rate limiting
- Use specialized tools like Webparsers for automated Glassdoor scraping with anti-blocking features
Project Setup
In this tutorial, we’ll utilize Python along with several popular community packages:
- httpx – an HTTP client library that enables communication with glassdoor.com’s servers
- parsel – an HTML parsing library, though we’ll perform minimal HTML parsing and primarily work with JSON data directly
These packages can be installed easily using the pip command:
$ pip install httpx parsel
Alternatively, you can substitute httpx with any other HTTP client package such as requests, as we’ll only need basic HTTP functions that are largely interchangeable across libraries. For parsel, another excellent alternative is the beautifulsoup package.
How to Remove Glassdoor Overlay
When browsing Glassdoor, you’ll inevitably encounter an overlay requesting user login:
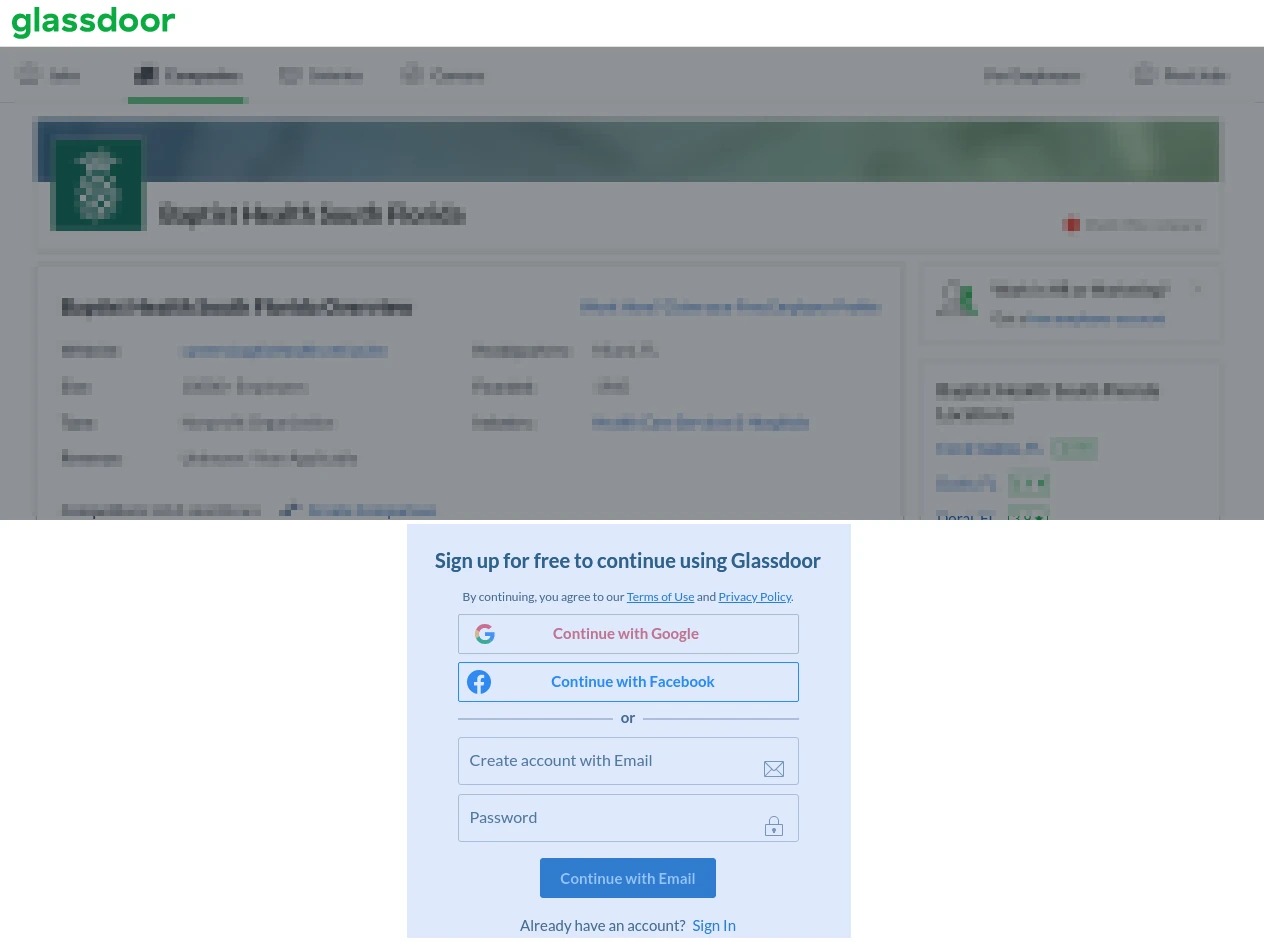
All content remains accessible beneath the overlay – it’s simply covered up. When scraping, our parsing tools can still locate this data:
import httpx
from parse import Selector

response = httpx.get(
    "https://www.glassdoor.com/Overview/Working-at-eBay-EI_IE7853.11,15.htm"
)
selector = Selector(response.text)
# find description in the HTML:
print(selector.css('[data-test="employerDescription"]::text').get())
# will print:
# eBay is where the world goes to shop, sell, and give. Every day, our professionals connect millions of buyers and sellers around the globe, empowering people and creating opportunity. We're on a mission to build a better, more connected form of commerce that benefits individuals
Glassdoor is known for its high blocking rate. If you’re receiving null values while executing Python code, you’re likely being blocked. Instead, consider using Webparsers code alternatives to avoid Glassdoor scraping blocks.
During development, we want to view and inspect the web page. We can easily remove the overlay using a bit of JavaScript:
function addGlobalStyle(css) {
    var head, style;
    head = document.getElementsByTagName('head')[0];
    if (!head) { return; }
    style = document.createElement('style');
    style.type = 'text/css';
    style.innerHTML = css;
    head.appendChild(style);
}

addGlobalStyle("#HardsellOverlay {display:none !important;}");
addGlobalStyle("body {overflow:auto !important; position: initial !important}");

window.addEventListener("scroll", event => event.stopPropagation(), true);
window.addEventListener("mousemove", event => event.stopPropagation(), true);
This script applies global CSS styles to hide the overlay and can be executed through the web browser’s developer tools console (F12 key, console tab).
Alternatively, it can be added to the bookmarks toolbar as a bookmarklet: simply drag this link: glassdoor overlay remover to your bookmarks toolbar and click it to remove the overlay at any time.
Selecting Region
Glassdoor operates globally with most content being region-specific. For instance, viewing eBay’s Glassdoor profile on glassdoor.co.uk will display only job listings relevant to the United Kingdom.
To select regions during web scraping, we can supply a cookie containing the selected region’s ID:
from parsel import Selector
import httpx

france_location_cookie = {"tldp": "6"}
response = httpx.get(
    "https://www.glassdoor.com/Overview/Working-at-eBay-EI_IE7853.11,15.htm",
    cookies=france_location_cookie,
    follow_redirects=True,
)
selector = Selector(response.text)
# find employee count in the HTML:
print(selector.css('[data-test="employer-size"]::text').get())
# will print:
# Plus de 10 000 employés
Some pages use URL parameters which we’ll address in the web scraping sections of this article.
Scraping Glassdoor Company Data
This tutorial focuses on extracting company information including company overviews, job listings, reviews, and more. The techniques covered here apply to virtually any other data page on glassdoor.com.
Company IDs
Before scraping specific company data, we need to identify their internal Glassdoor ID and name. We can use Glassdoor’s search page recommendations for this purpose.
For example, searching for “eBay” reveals a list of companies with their corresponding IDs.
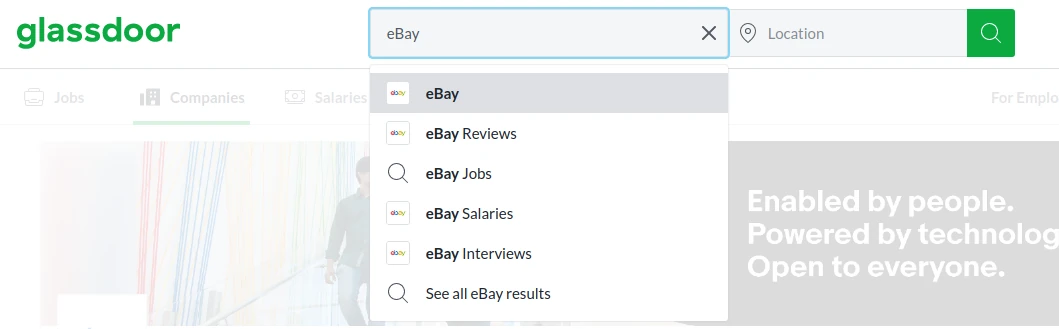
To scrape this information in Python, we can utilize the typeahead API endpoint:
import json
import httpx


def find_companies(query: str):
    """find company Glassdoor ID and name by query. e.g. "ebay" will return "eBay" with ID 7853"""
    result = httpx.get(
        url=f"https://www.glassdoor.com/api-web/employer/find.htm?autocomplete=true&maxEmployersForAutocomplete=50&term={query}",
    )
    data = json.loads(result.content)
    return data

print(find_companies("ebay"))
[“eBay”, “7853”]
Now that we can easily retrieve company name and numeric IDs, we can begin scraping company job listings, reviews, salaries, and other data.
Company Overview
Let’s begin our scraper by extracting company overview data.
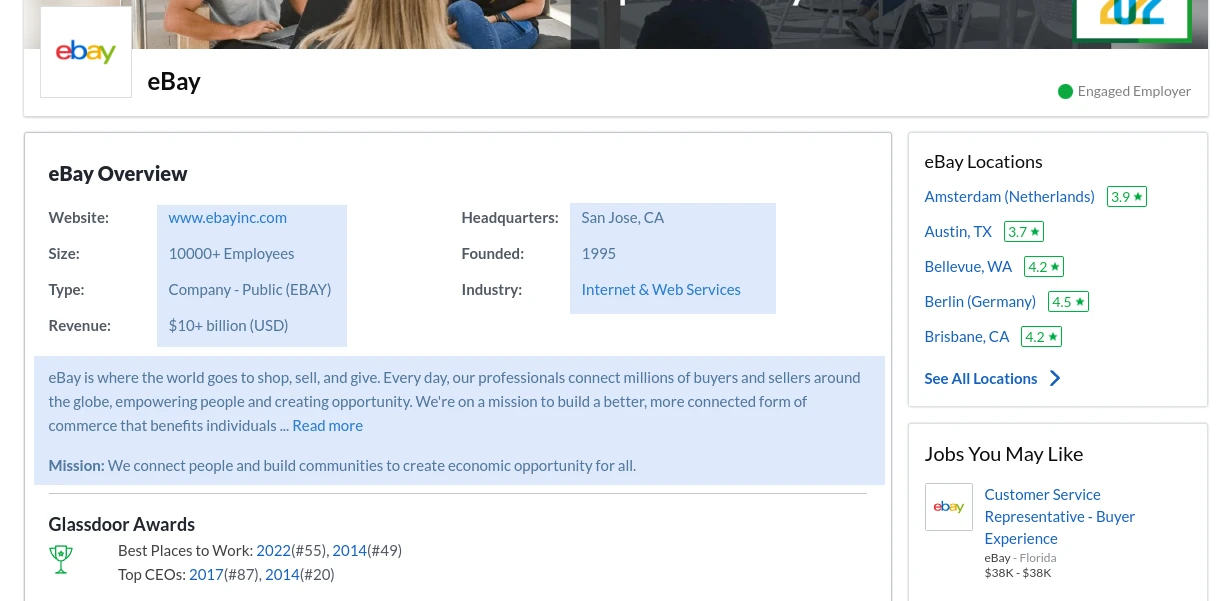
To scrape these details, we need either the company page URL or can generate the URL using company ID name and number.
import httpx
from parsel import Selector

company_name = "eBay"
company_id = "7671"

url = f"https://www.glassdoor.com/Overview/Working-at-{company_name}-EI_IE{company_id}.htm"
response = httpx.get(
    url,
    cookies={"tldp": "1"},  # use cookies to force US location
    follow_redirects=True
)
sel = Selector(response.text)
print(sel.css("h1::text").get())
To parse company data, we can either parse the rendered HTML using traditional parsing tools like BeautifulSoup. However, since Glassdoor uses Apollo GraphQL to power their website, we can extract hidden JSON web data from the page source.
The advantage of scraping Glassdoor through hidden web data is accessing the complete dataset of all available page data. This means we can extract more data than what’s visible on the page, and it’s already structured for us.
Let’s examine how to accomplish this with Python:
import re
import httpx
import json


def extract_apollo_state(html):
    """Extract apollo graphql state data from HTML source"""
    data = re.findall('apolloState":\s*({.+})};', html)[0]
    return json.loads(data)


def scrape_overview(company_name: str, company_id: int) -> dict:
    url = f"https://www.glassdoor.com/Overview/Worksgr-at-{company_name}-EI_IE{company_id}.htm"
    response = httpx.get(url, cookies={"tldp": "1"}, follow_redirects=True)
    apollo_state = extract_apollo_state(response.text)
    return next(v for k, v in apollo_state.items() if k.startswith("Employer:"))


print(json.dumps(scrape_overview("7853"), indent=2))
By parsing the embedded GraphQL data, we can easily extract the entire company dataset with just a few lines of code!
Let’s examine how to apply this technique to scrape additional details such as jobs and reviews.
How to Scrape Glassdoor Job Listings
For scraping job listings, we’ll also examine embedded GraphQL data, though this time we’ll parse GraphQL cache rather than state data.
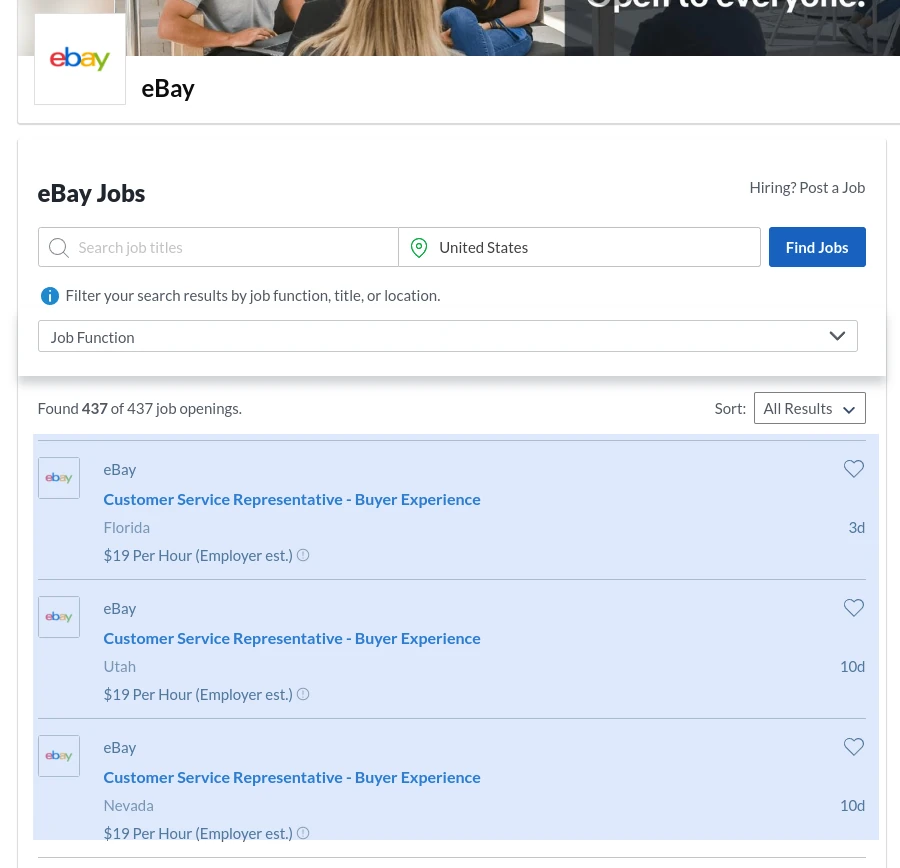
Let’s look at eBay’s Glassdoor jobs page.
Examining the page source reveals all job data is present in the JavaScript variable window.appCache within a hidden <script> node.
We can see that the hidden dataset contains more data than what’s visible on the page.
To extract it, we can use selectors and regular expressions:
def find_hidden_data(result: httpx.Response) -> dict:
    """
    Extract hidden web cache (Apollo Graphql framework) from Glassdoor page HTML
    It's either in NEXT_DATA script or direct apolloState js variable
    """
    # data can be in __NEXT_DATA__ cache
    selector = Selector(result.text)
    data = selector.css("script#__NEXT_DATA__::text").get()
    if data:
        data = json.loads(data)["props"]["pageProps"]["apolloCache"]
    else:  # or in direct apolloState cache
        data = re.findall(r'apolloState":\s*({.+})};', result.text)[0]
        data = json.loads(data)

    def _unpack_apollo_data(apollo_data):
        """
        Glassdoor uses Apollo GraphQL client and the dataset is a graph of references.
        This function unpacks the __ref references to actual values.
        """

        def resolve_refs(data, root):
            if isinstance(data, dict):
                if "__ref" in data:
                    return resolve_refs(root[data["__ref"]], root)
                else:
                    return {k: resolve_refs(v, root) for k, v in data.items()}
            elif isinstance(data, list):
                return [resolve_refs(i, root) for i in data]
            else:
                return data

        return resolve_refs(apollo_data.get("ROOT_QUERY") or apollo_data, apollo_data)

    return _unpack_apollo_data(data)
Our parser above takes the HTML text, locates a <script> node containing apolloCache or searches for apolloState throughout the HTML and extracts the cache objects. Let’s see how it handles Glassdoor’s job page:
import asyncio
import json
import httpx
import re
from typing import Dict, List, Tuple, Optional
from parsel import Selector
from urllib.parse import urljoin

session = httpx.AsyncClient(
    timeout=httpx.Timeout(30.0),
    cookies={"tldp": "1"},
    follow_redirects=True,
)

def find_hidden_data(result: httpx.Response) -> dict:
    """
    Extract hidden web cache (Apollo Graphql framework) from Glassdoor page HTML
    It's either in NEXT_DATA script or direct apolloState js variable
    """
    # data can be in __NEXT_DATA__ cache
    selector = Selector(result.text)
    data = selector.css("script#__NEXT_DATA__::text").get()
    if data:
        data = json.loads(data)["props"]["pageProps"]["apolloCache"]
    else:  # or in direct apolloState cache
        data = re.findall(r'apolloState":\s*({.+})};', result.text)[0]
        data = json.loads(data)

    def _unpack_apollo_data(apollo_data):
        """
        Glassdoor uses Apollo GraphQL client and the dataset is a graph of references.
        This function unpacks the __ref references to actual values.
        """

        def resolve_refs(data, root):
            if isinstance(data, dict):
                if "__ref" in data:
                    return resolve_refs(root[data["__ref"]], root)
                else:
                    return {k: resolve_refs(v, root) for k, v in data.items()}
            elif isinstance(data, list):
                return [resolve_refs(i, root) for i in data]
            else:
                return data

        return resolve_refs(apollo_data.get("ROOT_QUERY") or apollo_data, apollo_data)

    return _unpack_apollo_data(data)


def parse_jobs(result: httpx.Response) -> Tuple[List[Dict], List[str]]:
    """Parse Glassdoor jobs page for job data and other page pagination urls"""
    cache = find_hidden_data(result)
    job_cache = next(v for k, v in cache.items() if k.startswith("jobListings"))
    jobs = [v["jobview"]["header"] for v in job_cache["jobListings"]]
    other_pages = [
        urljoin(result.context["url"], page["urlLink"])
        for page in job_cache["paginationLinks"]
        if page["isCurrentPage"] is False
    ]
    return jobs, other_pages


def change_page(url: str, page: int) -> str:
    """update page number in a glassdoor url"""
    new = re.sub("(?:_P\d+)*.htm", f"_P{page}.htm", url)
    assert new != url
    return new


async def scrape_jobs(employer_name: str, employer_id: str, max_pages: Optional[int] = None) -> List[Dict]:
    """Scrape job listings"""
    # scrape first page of jobs:
    first_page = await session.get(
        url=f"https://www.glassdoor.com/Jobs/{employer_name}-Jobs-E{employer_id}.htm?filter.countryId={session.cookies.get('tldp') or 0}",
    )
    jobs, other_page_urls = parse_jobs(first_page)

    _total_pages = len(other_page_urls) + 1
    if max_pages and _total_pages > max_pages:
        other_page_urls = other_page_urls[:max_pages]

    print(f"scraped first page of jobs, scraping remaining {_total_pages - 1} pages")
    other_pages = [
        session.get(
            url=change_page(first_page.url, page),
        )
        for page in range(2, _total_pages + 1)
    ]
    for result in await asyncio.gather(*other_pages):
        jobs.extend(parse_jobs(result)[0])
    return jobs


async def main():
    jobs = await scrape_jobs("eBay", "7853")
    print(json.dumps(jobs, indent=2))
Above, we have a scraper that implements a standard pagination scraping algorithm:
- Scrape the first jobs page
- Extract GraphQL cache for jobs data
- Parse HTML for total page count
- Scrape remaining pages concurrently
Running our scraper should retrieve all job listings quickly!
Now that we understand Glassdoor’s functionality, let’s examine how to extract other details available in the GraphQL cache, such as reviews.
How to Scrape Glassdoor Company Reviews
To scrape reviews, we’ll explore another GraphQL feature – page state data.
Similar to finding GraphQL cache in page HTML, we can also locate GraphQL state data.
Just like with cache, state data contains much more information than what’s visible on the page.
To scrape reviews, we can parse GraphQL state data containing all reviews, review metadata, and numerous other data details:
import asyncio
import re
import json
from typing import Tuple, List, Dict
import httpx


def extract_apollo_state(html):
    """Extract apollo graphql state data from HTML source"""
    data = re.findall('apolloState":\s*({.+})};', html)[0]
    data = json.loads(data)
    return data


def parse_reviews(html) -> Tuple[List[Dict], int]:
    """parse jobs page for job data and total amount of jobs"""
    cache = extract_apollo_state(html)
    xhr_cache = cache["ROOT_QUERY"]
    reviews = next(v for k, v in xhr_cache.items() if k.startswith("employerReviews") and v.get("reviews"))
    return reviews


async def scrape_reviews(employer: str, employer_id: str, session: httpx.AsyncClient):
    """Scrape job listings"""
    # scrape first page of jobs:
    first_page = await session.get(
        url=f"https://www.glassdoor.com/Reviews/{employer}-Reviews-E{employer_id}.htm",
    )
    reviews = parse_reviews(first_page.text)
    # find total amount of pages and scrape remaining pages concurrently
    total_pages = reviews["numberOfPages"]
    print(f"scraped first page of reviews, scraping remaining {total_pages - 1} pages")
    other_pages = [
        session.get(
            url=str(first_page.url).replace(".htm", f"_P{page}.htm"),
        )
        for page in range(2, total_pages + 1)
    ]
    for page in await asyncio.gather(*other_pages):
        page_reviews = parse_reviews(page.text)
        reviews["reviews"].extend(page_reviews["reviews"])
    return reviews
Other Glassdoor Scraping Details
The embedded GraphQL data parsing techniques learned through Glassdoor review and job scraping can be applied to scrape other company details like salaries, interviews, benefits, and photos.
For example, we can scrape Glassdoor salary data using the same approach we used for reviews:
import httpx
import json
import asyncio
from typing import Dict, Optional


def parse_salaries(result) -> Dict:
    """Parse Glassdoor salaries page for salary data"""
    cache = find_hidden_data(result)
    salaries = next(v for k, v in cache.items() if k.startswith("aggregatedSalaryEstimates") and v.get("results"))
    return salaries


async def scrape_salaries(session: httpx.AsyncClient, url: str, max_pages: Optional[int] = None) -> Dict:
    """Scrape Glassdoor Salary page for salary listing data (with pagination)"""
    print("scraping salaries from {}", url)
    first_page = await session.get(url)
    assert first_page.status_code == 200, "request is blocked, use Webparsers code tab"
    salaries = parse_salaries(first_page)
    total_pages = salaries["numPages"]
    if max_pages and total_pages > max_pages:
        total_pages = max_pages

    print("scraped first page of salaries of {}, scraping remaining {} pages", url, total_pages - 1)

    other_pages = [
        session.get(
            url=change_page(str(first_page.url), page=page)
        )
        for page in range(2, total_pages + 1)
    ]
    for result in await asyncio.gather(*other_pages):
        salaries["results"].extend(parse_salaries(result)["results"])
    return salaries
By understanding Glassdoor’s web infrastructure, we can easily collect all publicly available company datasets on Glassdoor.
However, when collecting this data at scale, we’re likely to encounter blocking, so let’s examine how to avoid blocking using Webparsers API.
Bypass Glassdoor Scraping Blocking
Webparsers offers several powerful features that help circumvent Glassdoor scraper blocking:
- Anti Scraping Protection Bypass
- JavaScript Rendering
- 190M Pool of Residential or Mobile Proxies
For this, we’ll use the scrapfly SDK python package. To start, install scrapfly-sdk using pip:
$ pip install scrapfly-sdk
To convert our httpx-powered code to use the SDK, we simply replace our httpx requests with SDK ones:
To convert our httpx-powered code to use the SDK, we simply replace our httpx requests with SDK ones:

from scrapfly import ScrapflyClient, ScrapeConfig

client = ScrapflyClient(key='YOUR_SCRAPFLY_KEY')
result = client.scrape(ScrapeConfig(
    url="https://www.glassdoor.com/Salary/eBay-Salaries-E7853.htm",
    # we can enable anti-scraper protection bypass:
    asp=True,
    # or select proxies from specific countries:
    country="US",
    # and change proxy types:
    proxy_pool="public_residential_pool",
))
For an extended example of using scrapfly to scrape Glassdoor, see the Full Scraper Code section.
FAQ
To wrap up this guide, let’s address some frequently asked questions about web scraping Glassdoor.
Is it legal to scrape Glassdoor?
Yes. Data displayed on Glassdoor is publicly available, and we’re not extracting private information. Scraping Glassdoor.com at slow, respectful rates falls under ethical scraping practices. However, attention should be paid to GDPR compliance in the EU when scraping user-submitted data such as reviews. For more information, see our Is Web Scraping Legal? article.
Can I scrape Glassdoor Reviews without login?
Yes, Glassdoor reviews are public and accessible without login requirements, though Glassdoor’s front-end limits the number of visible reviews or blocks the view with a modal. The modal can be disabled when scraping or viewing with the JavaScript mentioned in this article, and paging limits don’t apply to scrapers.
How to find all company pages listed on Glassdoor?
Glassdoor contains over half a million US companies alone but lacks a sitemap. It does contain multiple limited directory pages like the directory for US companies. Unfortunately, directory pages are limited to a few hundred pages, though with crawling and filtering, it’s possible to discover all pages.
Another approach covered in this Glassdoor web scraping tutorial is discovering company pages through company IDs. Each Glassdoor company is assigned an incremental ID ranging from 1000-1,000,000+. Using HEAD-type requests, we can easily test each ID to determine whether they lead to company pages.
How to view Glassdoor without account?
To view Glassdoor pages without an account, disable the Glassdoor overlay using JavaScript. In this article, we use a simple JavaScript bookmarklet, but this can be done with any tools capable of executing JavaScript, like the browser console.
Latest Glassdoor Scraper Code
Glassdoor Scraping Summary
In this web scraping tutorial, we’ve examined how to scrape Glassdoor for various details including metadata, reviews, job listings, and salaries.
We accomplished this by leveraging GraphQL cache and state data, which we extracted using several generic web scraping algorithms in plain Python.
Legal Disclaimer and Precautions
This tutorial covers popular web scraping techniques for educational purposes. Interacting with public servers requires diligence and respect, and here’s a good summary of what not to do:
- Do not scrape at rates that could damage the website.
- Do not scrape data that’s not publicly available.
- Do not store PII of EU citizens who are protected by GDPR.
- Do not repurpose entire public datasets which can be illegal in some countries.
Webparsers does not offer legal advice, but these are good general rules to follow in web scraping. For more guidance, you should consult a lawyer.